
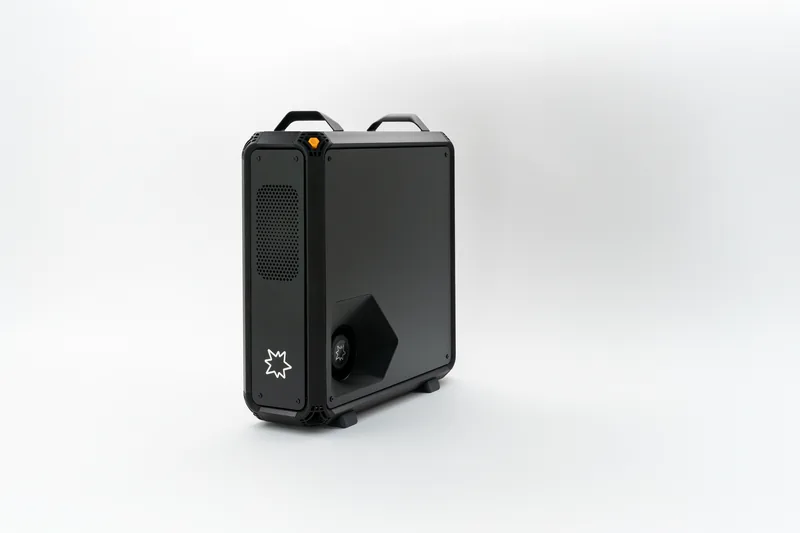
Your data stays private
Client files, code and unreleased ideas never reach a cloud model. Runs fully offline, stores no prompts, needs no account with us.
Backed by Y Combinator
Partners
Hardware
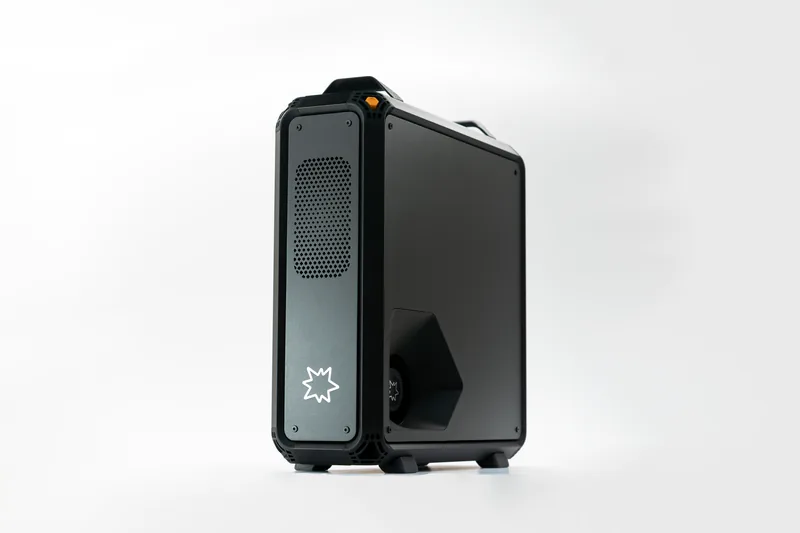
Client files, code and unreleased ideas never reach a cloud model. Runs fully offline, stores no prompts, needs no account with us.
Point Claude Code, Codex, OpenCode or Pi at its Anthropic and OpenAI compatible API. Repos, tickets and docs stay on your network.
Research bots, automations and agent teams, running 24/7. Pay once, share it with your team, and forget per-token bills and rate limits.
The engine, custom kernels, speculative decoding and tuned models come installed for this exact hardware. Plug it in, pair it, and it runs at full speed.
Performance
Over 2× the reported DGX Spark decode speed.
Dense
From one user's DFlash2 run on a long prompt. DGX Spark and Mac M5 Max are public records with their own setups.
DetailsMoE
Measured on Lucebox at 2K context. DGX Spark and Mac M5 Max are public records with their own setups.
Details
Setup
Visit lucebox.com/setup from a nearby laptop or Android device. There is no app or CLI to install.
The onboarding page sends Wi-Fi, account, and optional Tailscale settings to the box over encrypted Bluetooth.
The local dashboard checks the machine, installs the qualified model profile, and starts the private API.
Enable Lucebox Connect once, then open any supported app from Manage with a single click.
Tokens per app and model, recent requests, and live machine meters. Prompts and replies are never stored.


Order
$5,999€5,999 USD per machine / shipping includedEUR + VAT per machine / shipping included
12 months of Lucebox Engine Pro included
$7,999€7,999 USD per machine / shipping includedEUR + VAT per machine / shipping included
Community
I like your stuff so far, keep going
this guy just cracked 134 tok/s on qwen 3.5-27b dense and 73 on new qwen 3.6-27b on a single 3090. open source moves at godspeed in 2026.
Interesting run w/ Dflash from the lucebox-hub guys
speculative PREFILL?????
I have tested some LLM server software for home PCs for Linux and Windows. Fastest and best for running home is Linux running 145 t/s, Lucebox. @pupposandro @luceboxai
PFlash just killed the 4-minute blank screen problem. 128K token prefill in 25 seconds, same GPU, same model, no compromises
Consumer-grade GPUs actually have sufficient hardware potential, general-purpose frameworks just waste most of it on overhead. Lucebox releases that potential through hand-written kernels, letting even a 2020 RTX 3090 rival Apple's latest chips on efficiency.
Crazy I was litteraly wondering how can I increase my token speed 10 min ago
Crazy what @pupposandro just dropped on Qwen3.5-27B. 207 tok/s on a single 3090 with Q4_K_M and full DFlash speculative? Chinese labs + ggml hacks are just cooking on consumer hardware right now. This is the kind of local win I like to see.
RTX 3090 ready for a new life! Bringing it to @luceboxai team to make some experiments together
github.com/Luce-Org/lucebox-hub looks promising as a way to run "dense" models (eg. Qwen 27B) more efficiently. It's janky, but on my 5090 laptop it seems to be ~2x more tok/s than llama.cpp
This is very very good work BRAVO. I love it
Nearly 10x faster! After finishing Decoding, it starts cranking through Prefill. The previous DFlash was already stunning enough, and now they've added PFlash. Speculative prefill, up to 10x speedup. Go try it right now.
First time reading about speculative prefill, and it's crazy. 257s down to 24s for a 128K prompt on a single RTX 3090. Great article, definitely go ahead and give this a read.
impressive... so this is what it looks like when you focus on a set ram limit and optimizing for a single model above everything
Our open source inference engine is used by engineers at





Blog
At the highest load each machine served, one Lucebox answered 58 image questions a minute (Qwen3.8-27B on its AMD Radeon AI PRO R9700 and the 284B DeepSeek V4 Flash Vision on its Strix Halo, at the same time) and an NVIDIA DGX Spark running llama.cpp 18. With the same Qwen model file and eight questions at once, the R9700 alone finishes 2.4x sooner.
AI inference and cooling designed together on the R9700: the model forecasts the work ahead, a learned thermal model picks the slowest safe fan speed. Chat silent, agent loops 29% and batch work 25% quieter, same peak temperatures and throughput.
DeepSeek V4 Flash on one Strix Halo, both engines on the same box on the same day: Lucebox ROCm is 17 to 47% faster on prefill and 28 to 47% faster on speculative decode than llama.cpp Vulkan at 8K, 32K and 123K, with plain decode measured on the same box too.
Asymmetric parallelism splits the full 284B model across the R9700 and the Strix Halo: 3.63× the decode speed of one DGX Spark, for 36% less than two.
Cold 64-token KV chunks page to host RAM bit-exact, so decode holds at 38.6 tok/s from 64K to 256K with unchanged accuracy.
The full 284B model runs from 128 GB of unified memory: up to 32 tok/s decode and roughly 250 tok/s indexed sparse prefill.
FAQ